



Hardware components | ||||||
 |
| × | 1 | |||
Software apps and online services | ||||||
 |
| |||||
Story :
Team Members:
Yumei Li
Yudai Chen
Chenfei Wang
Yiheng Chen
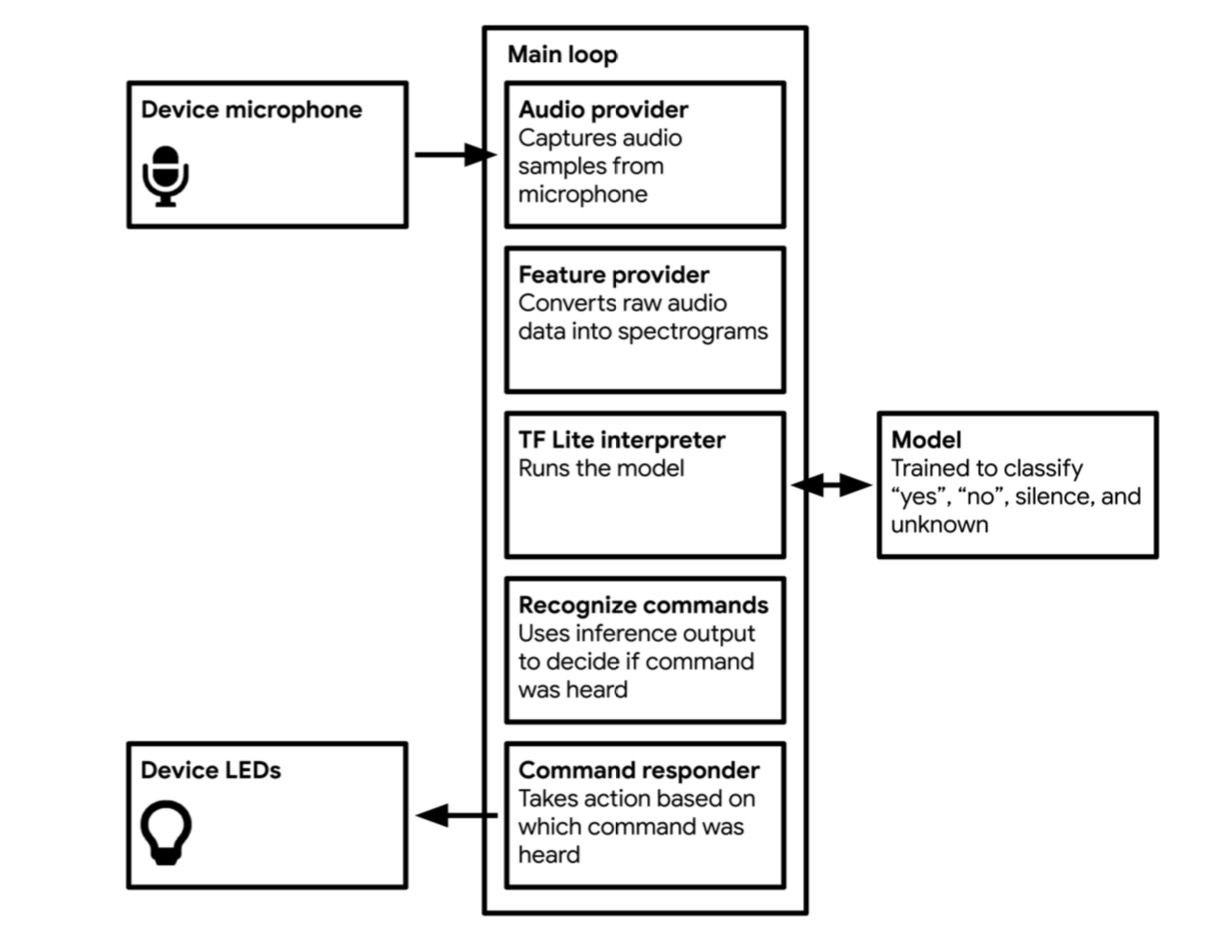
In this project, We built an embedded application that uses a 18 KB model, trained on a dataset of speech commands, to classify spoken audio. The model is trained to recognize the words “yes” and “no”, and is also capable of classify unknown words.Our application will listen to its surroundings with a microphone, and indicate when it has detected a word by lighting an LED or displaying data on a screen, depending on the capabilities of the device.
Steps:
1. Obtains an input
2. Pre-processes the input to extract features suitable to feed into a model
3. Runs inference on the processed input
4. Post-processes the model’s output to make sense of it
5. Uses the resulting information to make things happen.
Result:
Then we followed steps above to understand the code and deployed it to the sense. Green light will activate for 3 seconds for 'yes', and red light will activate for 3 seconds for 'no'. Here is the demo of our application.


Comments